Your AI Scored 100%. Half the Evaluation Is Missing.
Audit missing model-evaluation grades before trusting a perfect score. Reproduce a CSV coverage report with 11 tests and explicit denominators.
BY JASON EAD
Original guides and analysis about coding tools, models, GitHub projects, agents, and creative AI workflows.
Audit missing model-evaluation grades before trusting a perfect score. Reproduce a CSV coverage report with 11 tests and explicit denominators.
Build a local SQLite FTS5 procedure-search baseline. Reproduce useful keyword hits and a revealing synonym miss before comparing more complex retrieval.
Include human review time when comparing AI workflows. Use a tested decimal calculator and a task-trial record, with clearly fictional inputs and no model-performance claims.
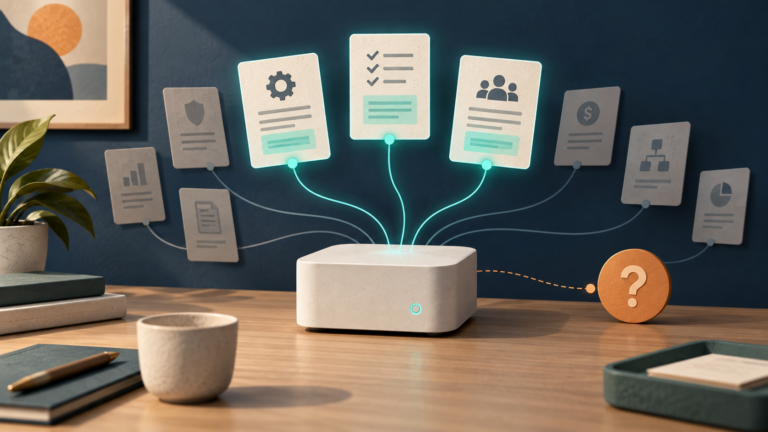
Run a local embedding model over business procedures, return traceable sources and test the questions your library cannot answer. Includes complete Python code.
Build a tested Python scorer for AI ticket routing. Use fictional cases, severity weights and strict run checks to catch regressions hidden by overall accuracy.
Build a tested validation boundary for AI-generated business data with Pydantic, strict types, source checks and a separate human-review step.